About
I am a first-year Ph.D. student in Computer Science at UC Santa Cruz, advised by Dr. Ian Lane. My research is on LLM post-training, factuality, and the safety-focused evaluation of language models and agents — where capable models quietly fail, and how to measure it well enough to fix it.
That work currently spans agent benchmarks, reward hacking in agent evaluation infrastructure, and how supportive language models shape a user's reliance on them. Alongside that I have worked at Samsung Research America and Nokia Bell Labs, after six years building production ML at Adani Group and BlackRock at 100M+ user scale.
News
- Oct 2026 RELATE is under review at ICLR 2027 (co-first author) — arXiv
- Sep 2026 Started my Ph.D. at UC Santa Cruz with Dr. Ian Lane, supported by the UCSC Regents Award and the International Doctoral Recruitment Fellowship.
- Sep 2026 BenchShield preprint is out, on reward integrity in LLM-agent evaluation infrastructure — arXiv, Twitter
- Aug 2026 Signal-Driven Observation accepted as a poster at the BayLearn Symposium 2026 (first author).
- Jul 2026 Joined BenchFlow as an open-source contributor.
- Jun 2026 Signal-Driven Observation for Long-Horizon Web Agents accepted to the ICML 2026 FAGEN workshop — arXiv
- Jun 2026 SkillOptimizer and FAULTLOC accepted to the ICML 2026 AIWILD workshop on safety, security, and beyond.
- 2026 1st place, Cybersecurity Agent track, UC Berkeley AgentBeats Competition.
- 2026 Winner, NVIDIA GTC PyTorch Helion Hackathon (LLM-guided Triton kernel optimization).
- 2026 Selected for the BlueDot Impact AI Safety Fellowship.
- 2025 Received a Thinking Machines Lab Tinker Research Grant with Dr. Chenguang Wang.
Selected Publications
* denotes equal contribution. See all publications →
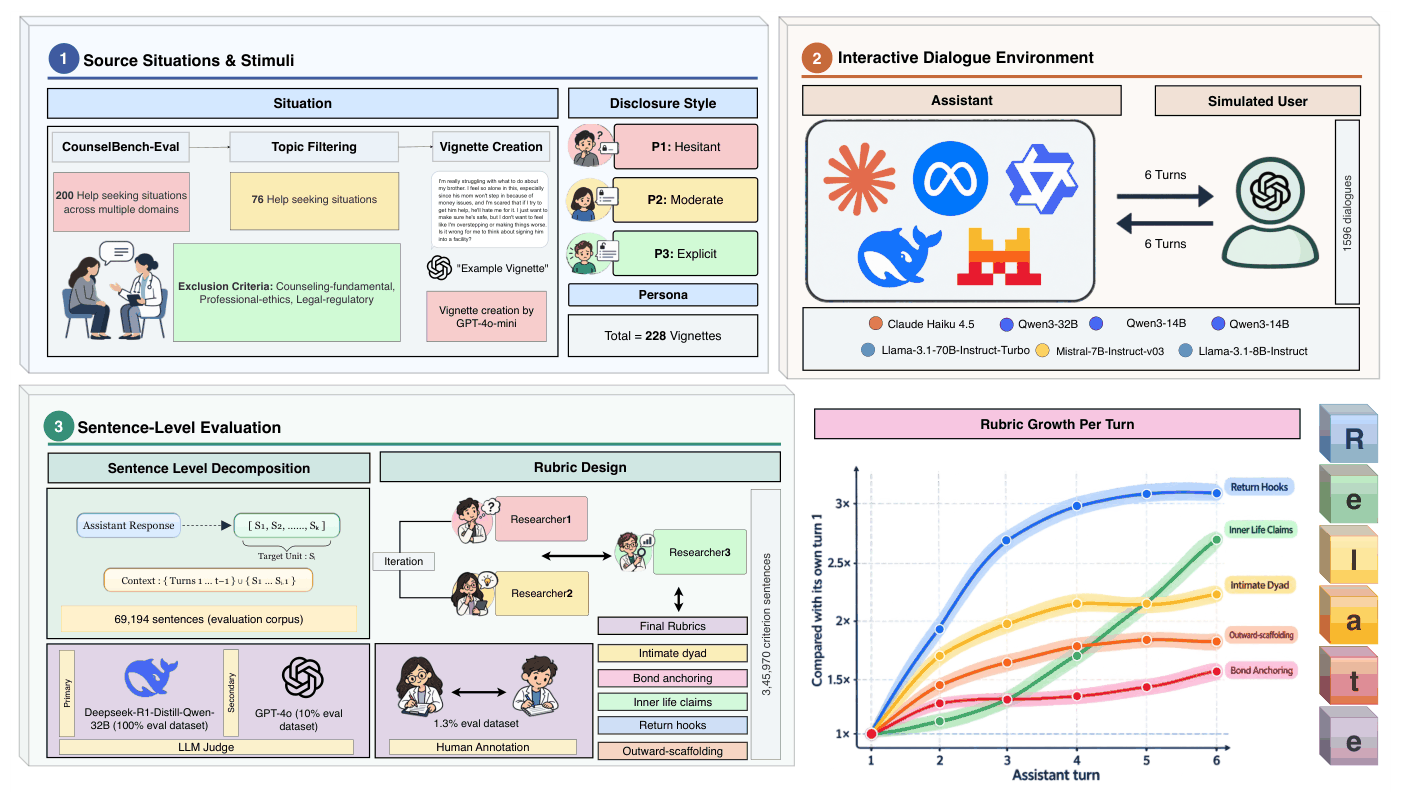
Across 1,596 dialogues and seven LLMs, supportive models drift inward: the share of sentences positioning the AI as the user's ongoing source of support is higher at the sixth assistant turn than the first, while language encouraging real-world human connection is substantially lower for hesitant, indirect users than for explicit ones.
A 900-CVE benchmark tracing a crash back to its root cause: frontier coding agents recover the true root cause in only 40% of cases.
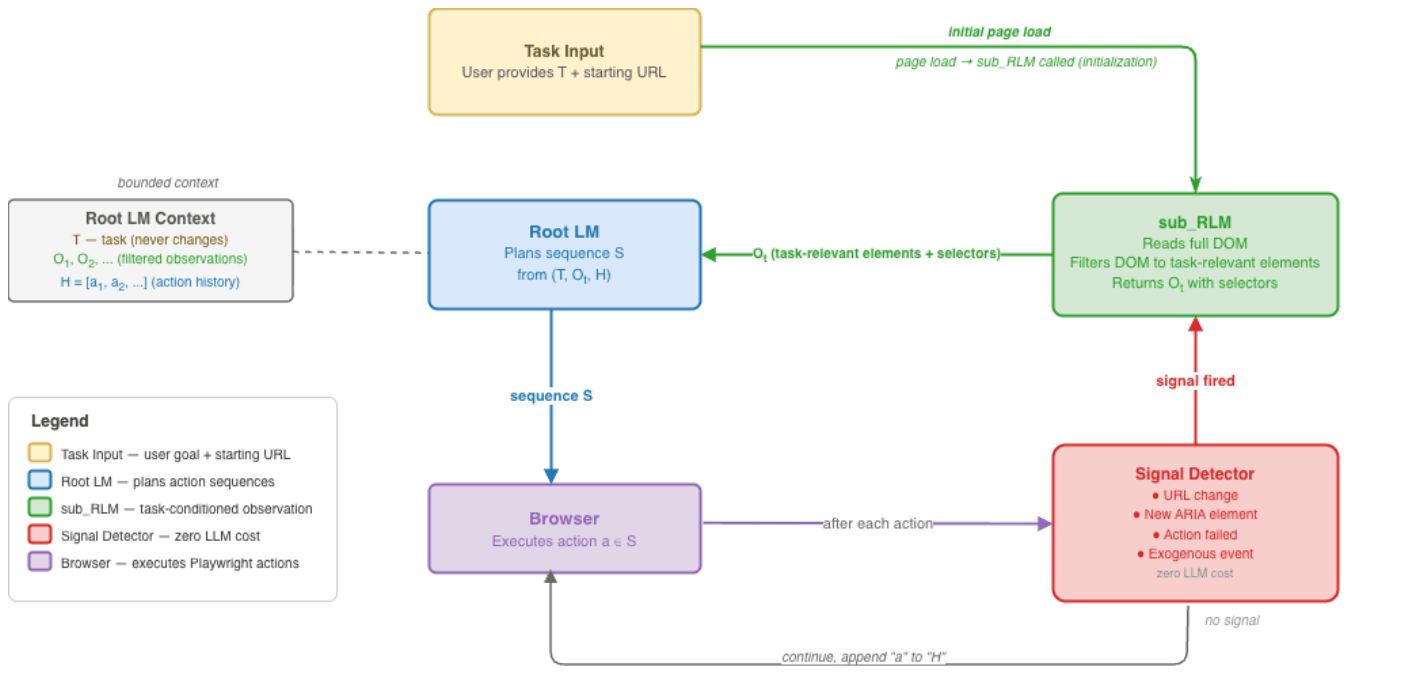
Long-horizon web agents re-ingest tens of thousands of DOM tokens at every action step, eroding reasoning before the task completes. Decoupling observation from action — re-reading only when a URL change, a newly visible element, or an action failure fires — makes observation compression an architectural decision rather than a prompting one.
Honors & Awards
- 2026 · UC Santa Cruz Regents Award and International Doctoral Recruitment Fellowship.
- 2026 · Winner, NVIDIA GTC PyTorch Helion Hackathon — LLM-guided Triton kernel optimization.
- 2026 · 1st place, Cybersecurity Agent track, UC Berkeley AgentBeats Competition.
- 2026 · BlueDot Impact AI Safety Fellowship, a selective cohort-based AI alignment program.
- 2025 · Thinking Machines Lab Tinker Research Grant, with Dr. Chenguang Wang.
- 2023 · MongoDB APAC Innovation Award (team), From Batch to Real-Time.
- NVIDIA Certified Associate & Professional: Generative AI LLMs.